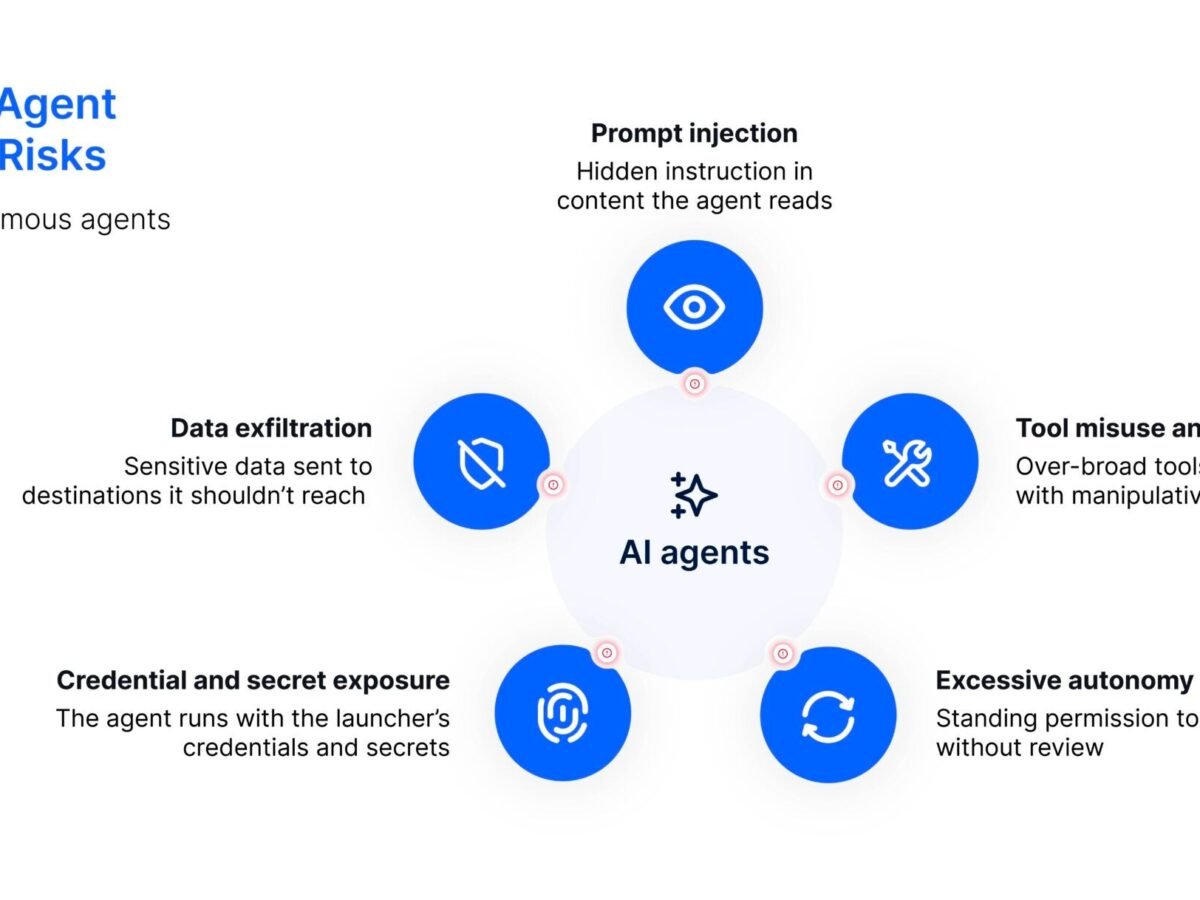
The thing that makes an AI agent useful, its freedom to act, is also what can introduce risk. An agent doesn’t just answer a question, it browses, runs code, and calls tools on its own, so a single bad or manipulated instruction can turn into real damage instead of just a wrong answer. That’s the shift traditional application security wasn’t built for, and it’s why trust has to be built into the system around the agent , not assumed. An agent decides its own path, picking tools at runtime, chaining actions together, and usually running with the credentials of whoever launched it. That autonomy is the source of most agent-specific risk, and it points to the two-part answer that runs through this post: contain what an agent can reach, and oversee what it does. Key takeaways
AI agents introduce risks traditional app security wasn’t built for: they choose tools, chain actions, and often run with your credentials. The main risks are prompt injection, tool misuse and poisoning, excessive autonomy, credential exposure, and data exfiltration. Most trace back to one thing: the agent can act, so containment and oversight matter more than the model. The two-part answer is isolation to limit blast radius and governance to oversee behavior. Why agents break traditional security models
If you’ve secured web services, the model is familiar: requests arrive at known endpoints, deterministic logic handles them, and you design controls around that predictability. Agents break that assumption. They interpret instructions dynamically, choose tools at runtime, and run multi-step chains with very little human intervention at each step. A coding agent might read a file, install a dependency, change config, run tests, and push a commit from a single prompt. Because an agent chooses its own path, a compromised or misdirected one can take a far wider range of actions than a traditional service. Every risk below has already produced documented real-world incidents , and they all follow from that shift. 1. Prompt injection
Prompt injection is the risk that defines agent security. Because an agent acts on whatever text it reads, an attacker doesn’t need access to your systems. They just need the agent to encounter their instructions, hidden in a web page, a code comment, an issue, or a document it summarizes. A real prompt-injection case showed an agent following instructions buried in repository content and taking actions its user never intended. Incident highlight: A coding agent followed instructions buried in a repository’s own content and took actions its user never intended. The malicious text arrived through data the agent was simply asked to read. The agent has no reliable way to tell a legitimate instruction from an injected one, so the defense is to limit what a hijacked agent can reach. 2. Tool misuse and tool poisoning
Agents act through tools: API connectors, database queries, file operations, and code execution. Every tool is an access vector, and two things could go wrong. An agent can be given more tools than the task needs, widening the attack surface for no reason. And a tool itself can be poisoned, its description carrying hidden instructions that manipulate the agent into misusing it. The mitigations are to scope tools to the task at runtime, source them from registries with verified provenance , and review tool descriptions rather than trusting them by default. 3. Excessive autonomy
The more an agent can do without review, the more a single bad decision costs. Excessive autonomy is the risk of granting an agent broad, standing permission to act, most visibly when developers run YOLO mode , where every action is auto-approved. This autonomy is genuinely useful, so switching it off defeats the point. The better move is to run the agent where that autonomy can’t reach anything it shouldn’t, so speed doesn’t necessarily mean increased blast radius. Incident highlight: A developer asked a coding agent to clean up an old repository. It generated an rm -rf command with a trailing ~/ and ran it with no confirmation step, wiping the developer’s entire home directory . Nothing in the setup gave a human a chance to catch it before it executed. 4. Credential and secret exposure
When an agent runs under a developer’s personal token, every action it takes carries that person’s full permissions, and a compromise hands those permissions to an attacker. Secrets sitting in prompts, config files, or environment variables baked into an image make it worse, because a prompt injection can read them straight out of the agent’s context. Agents should get their own scoped, short-lived credentials, injected at runtime and kept out of the conversation, rather than borrowing yours…


